
- by x32x01 ||

What if a $200 monthly Claude subscription could support AI coding activity equivalent to more than $9,000 in estimated API usage?
That's what one development team's Claude Code usage report showed after five weeks of work.
The interesting part isn't just the difference between the two numbers. It's how the team managed its AI workflow, reused cached context, and avoided wasting expensive model tokens on repetitive tasks.
Let's break down the actual numbers and the practical lessons developers can take from them.
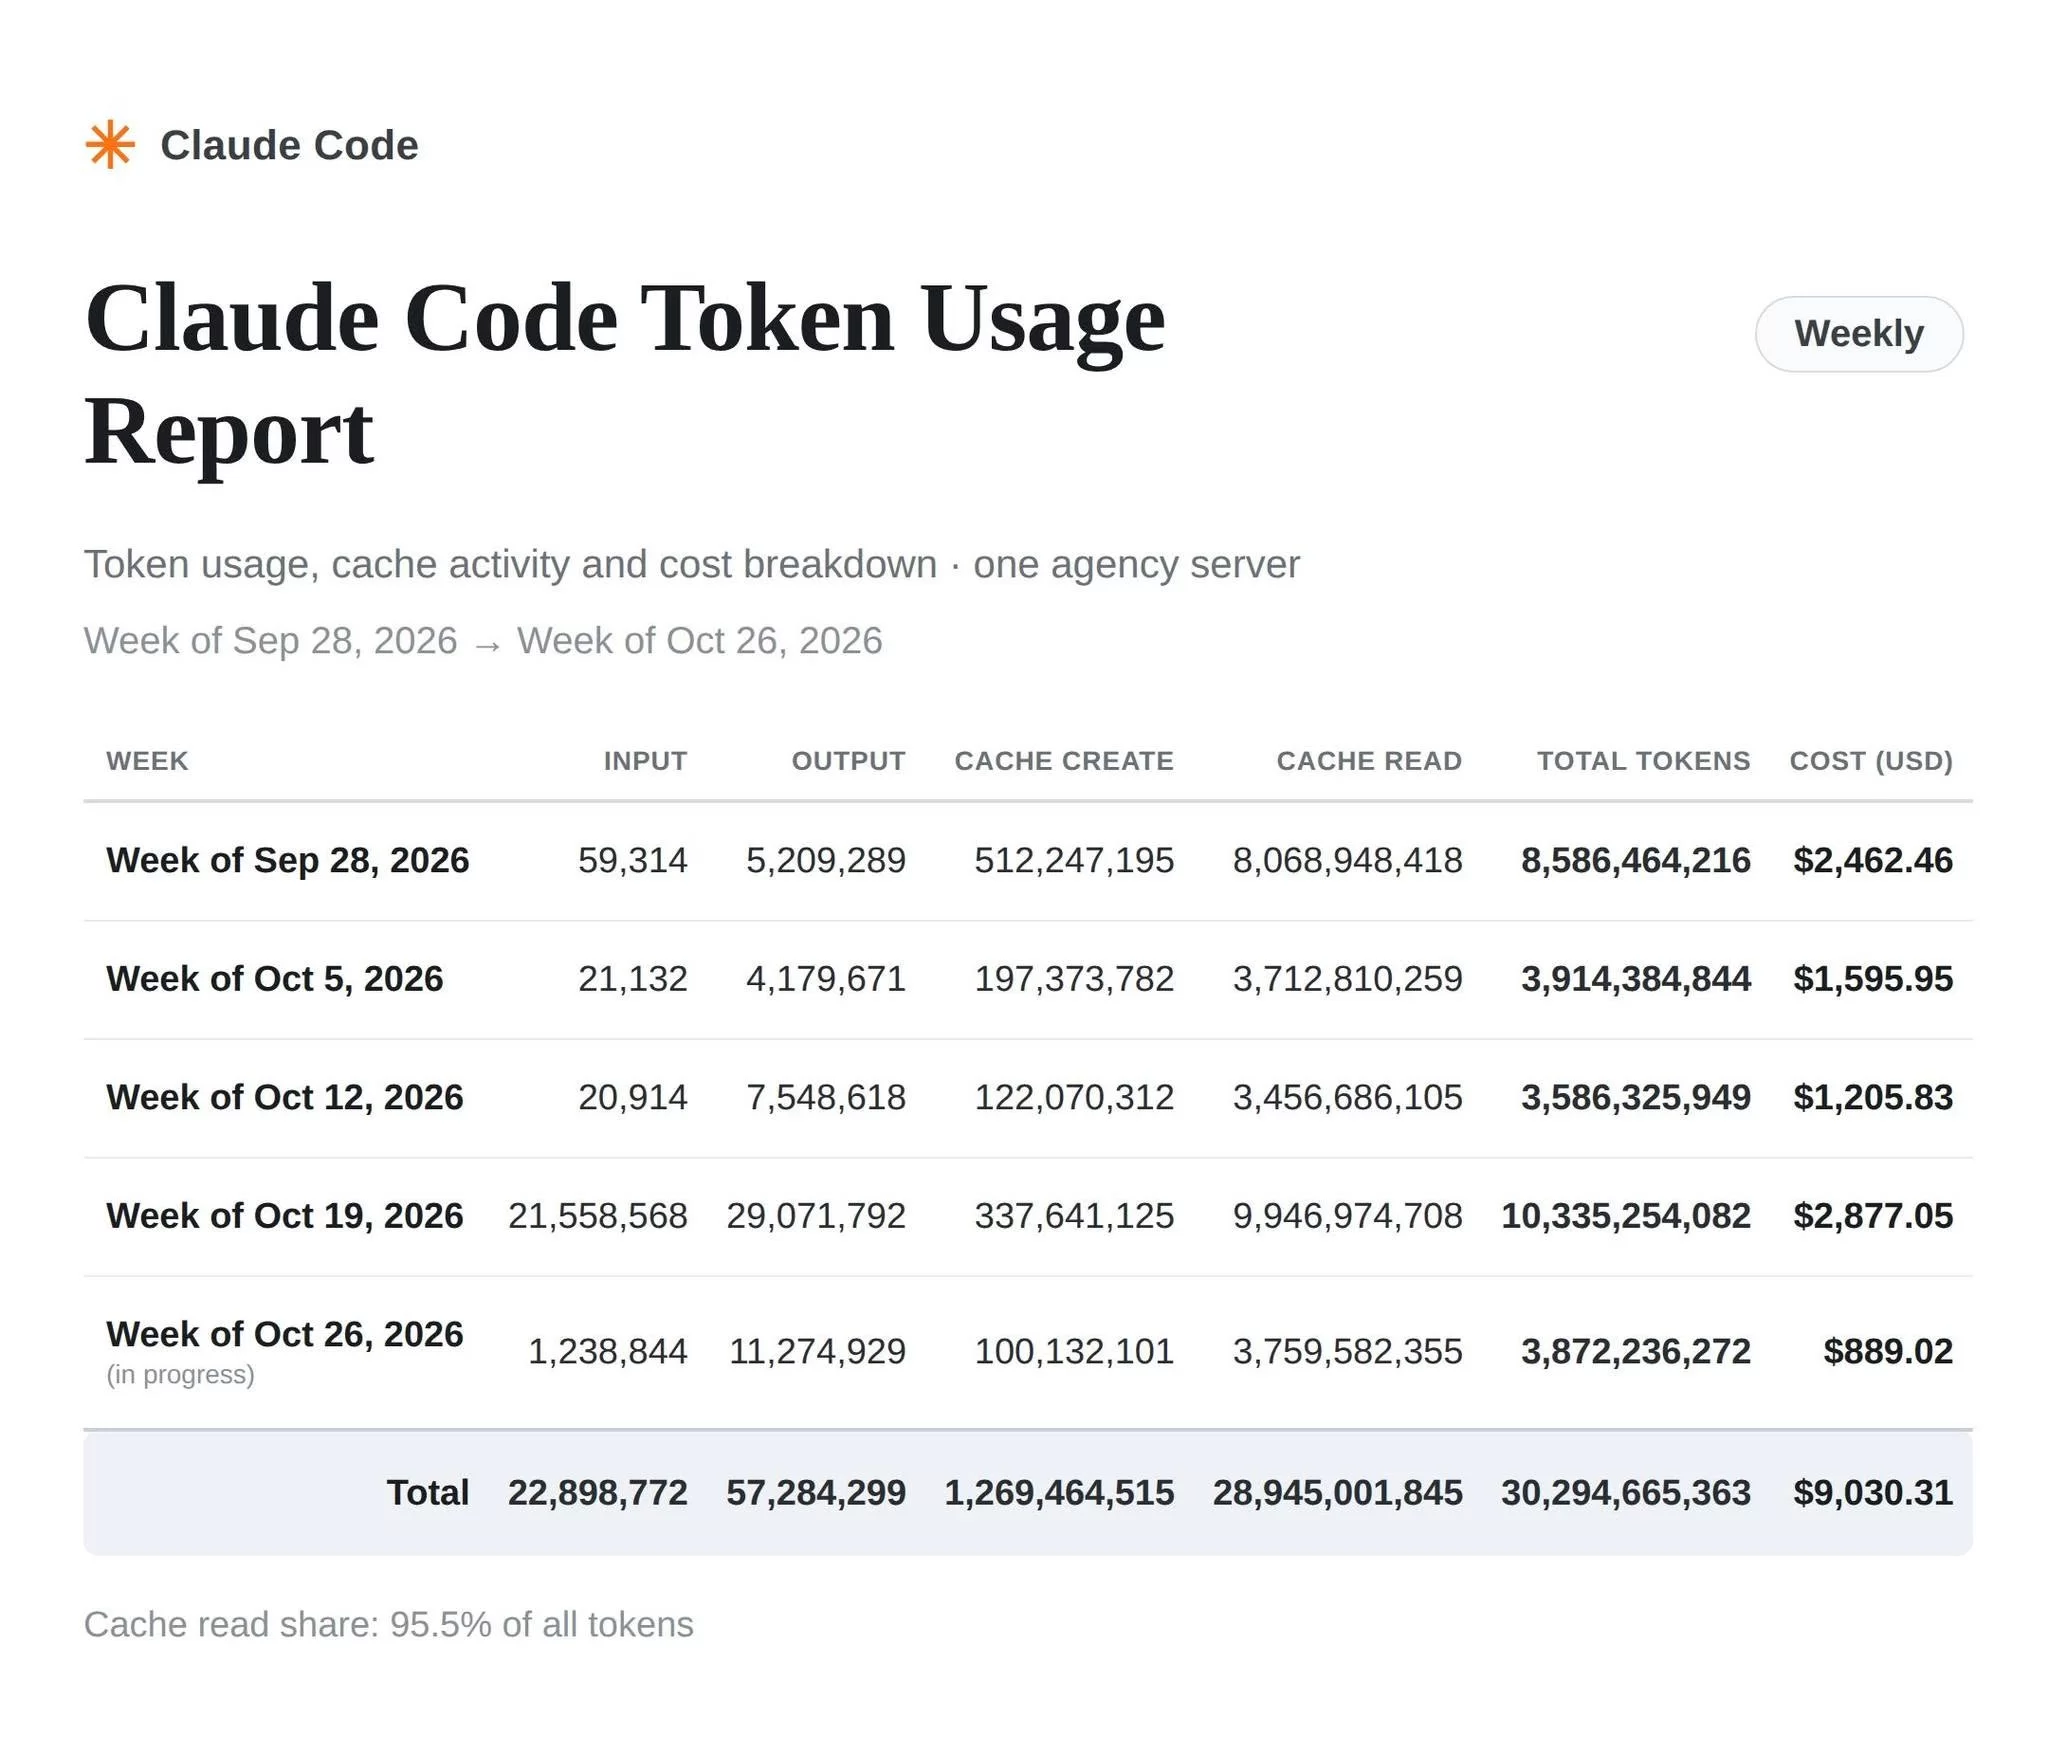
That's approximately 30.3 billion tokens, with nearly all reported token activity coming from cache reads.
The team used Claude's $200 monthly Max 20x subscription rather than paying for every request through a separately billed API workflow.
One important distinction: the $9,030 figure represents an estimated API-equivalent cost, not an actual bill or guaranteed savings. Subscription pricing and API billing are different models, and Claude subscriptions have usage limits.
Also, the reporting period covers 31 calendar days, so the exact subscription charges for that period depend on the billing dates.
Still, the report reveals something worth understanding: efficient context reuse can dramatically change the economics of AI-assisted development.
Imagine working on a large programming project.
Your AI assistant needs access to project instructions, documentation, source files, and other relevant context.
Without effective caching, repeatedly processing the same material can become expensive.
With prompt caching, eligible reusable content can be stored temporarily and referenced by subsequent requests.
For supported Claude models, standard cache reads are priced at 10% of the regular input-token rate when using the API.
That means:
1 million regular input tokens at a hypothetical $5 per million would cost $5, while 1 million cache-read tokens at 0.1x would cost $0.50.
The exact prices depend on the model and applicable caching configuration.
Caching isn't completely free. Creating cache entries also has a cost, and cached content must remain eligible for reuse.
However, when a development workflow repeatedly uses the same context, those cheaper cache reads can make a substantial difference.
It's this:
28,945,001,845 cache read tokens out of 30,294,665,363 total reported tokens.
That represents approximately 95.5% of the reported token activity.
In other words, the overwhelming majority of the measured tokens came from previously cached content.
This doesn't mean that 95.5% of the total API bill disappeared. Cache creation, uncached input, and output tokens have different pricing.
It does indicate that the team's workflow achieved extensive context reuse.
For developers who repeatedly work with large codebases, documentation, and persistent project instructions, this is an important efficiency metric.
They followed three practical habits.
Instead, it separated responsibilities:
For example, designing the architecture of a complex application may justify a more capable model.
Renaming variables, generating straightforward boilerplate, or performing a simple formatting task usually doesn't require the same level of reasoning.
The goal is to match model capability to task complexity.
However, model selection should also consider accuracy, review requirements, and the cost of correcting mistakes.
If a task can be expressed as a reliable script, there's often no reason to spend AI tokens performing it again and again.
Consider a project where you regularly need to:
Once implemented, a local script can execute without making additional AI requests.
It may still consume computing resources, but it doesn't require new model tokens unless AI calls are explicitly included.
A useful rule: If you repeatedly ask AI to perform the same predictable operation, consider automating it.
This makes development workflows faster, more consistent, and less dependent on token consumption.
Rather than unnecessarily rebuilding project context, they kept frequently reused instructions and project materials consistent.
This matters because prompt caching depends on matching eligible prompt content.
Even small changes to cached portions can prevent reuse of an existing cache entry.
For Claude Code users, practical habits include:
Cache reuse depends on factors such as matching prompt prefixes, cache lifetime, and how the application manages caching.
Likewise, keeping a conversation open indefinitely doesn't guarantee better performance or lower costs.
The objective is to preserve useful context without accumulating unnecessary information.
Project repository:
https://github.com/ccusage/ccusage
If you have Node.js and npm installed, you can run:
To inspect daily usage:
For monthly usage:
The report can help you understand your token consumption and estimated costs.
Pay particular attention to these metrics:
1. Cache Read Tokens
How much of your reported token activity comes from cached content?
2. Cache Creation Tokens
How much new content is being written into the cache?
3. Input and Output Tokens
How much uncached input is processed, and how much new content does the model generate?
4. Estimated Cost
What would the recorded usage cost under the pricing assumptions used by the reporting tool?
Remember that estimated API costs aren't necessarily equivalent to actual Claude subscription charges.
The team's experience is an interesting example of efficient subscription-based AI development, but it shouldn't be interpreted as a universal pricing guarantee.
Claude subscription plans and API usage have different billing structures.
A subscription doesn't provide unlimited API access, and usage may be subject to limits that vary depending on the plan, model, demand, and other conditions.
Likewise, the team's high cache-read percentage doesn't guarantee that another developer will achieve identical results.
Actual usage depends on factors such as project size, workflow design, model selection, and how frequently context can be reused.
The valuable lesson is not that every developer can replace a $9,000 API bill with a $200 subscription.
It's that poorly managed AI workflows can consume significantly more resources than necessary.
But it also highlights three useful ways to improve efficiency:
Look at your cache-read activity, identify repetitive operations, and check whether you're repeatedly processing information that could be reused.
Sometimes the biggest improvement doesn't come from buying more tokens.
It comes from using the tokens you already have more effectively.
That's what one development team's Claude Code usage report showed after five weeks of work.
The interesting part isn't just the difference between the two numbers. It's how the team managed its AI workflow, reused cached context, and avoided wasting expensive model tokens on repetitive tasks.
Let's break down the actual numbers and the practical lessons developers can take from them.
📊 Claude Code Usage: $200 vs. $9,030
According to a usage report generated with ccusage, the team recorded the following activity between September 28 and October 28:| Metric | Reported Value |
|---|---|
| Reporting period | September 28 - October 28 |
| Total tokens | 30,294,665,363 |
| Cache read tokens | 28,945,001,845 |
| Cache read percentage | 95.5% |
| Estimated API cost | $9,030.31 |
| Monthly subscription | $200 |
The team used Claude's $200 monthly Max 20x subscription rather than paying for every request through a separately billed API workflow.
One important distinction: the $9,030 figure represents an estimated API-equivalent cost, not an actual bill or guaranteed savings. Subscription pricing and API billing are different models, and Claude subscriptions have usage limits.
Also, the reporting period covers 31 calendar days, so the exact subscription charges for that period depend on the billing dates.
Still, the report reveals something worth understanding: efficient context reuse can dramatically change the economics of AI-assisted development.
💡 What Is Claude Prompt Caching?
Prompt caching allows Claude to reuse previously processed portions of a prompt instead of processing the same content from scratch every time.Imagine working on a large programming project.
Your AI assistant needs access to project instructions, documentation, source files, and other relevant context.
Without effective caching, repeatedly processing the same material can become expensive.
With prompt caching, eligible reusable content can be stored temporarily and referenced by subsequent requests.
For supported Claude models, standard cache reads are priced at 10% of the regular input-token rate when using the API.
That means:
1 million regular input tokens at a hypothetical $5 per million would cost $5, while 1 million cache-read tokens at 0.1x would cost $0.50.
The exact prices depend on the model and applicable caching configuration.
Caching isn't completely free. Creating cache entries also has a cost, and cached content must remain eligible for reuse.
However, when a development workflow repeatedly uses the same context, those cheaper cache reads can make a substantial difference.
Why the 95.5% Cache Read Ratio Matters
The most interesting number in the team's report isn't the total token count.It's this:
28,945,001,845 cache read tokens out of 30,294,665,363 total reported tokens.
That represents approximately 95.5% of the reported token activity.
In other words, the overwhelming majority of the measured tokens came from previously cached content.
This doesn't mean that 95.5% of the total API bill disappeared. Cache creation, uncached input, and output tokens have different pricing.
It does indicate that the team's workflow achieved extensive context reuse.
For developers who repeatedly work with large codebases, documentation, and persistent project instructions, this is an important efficiency metric.
🚀 Three Habits Behind an Efficient Claude Code Workflow
According to the team's account, its results weren't simply the outcome of using an expensive AI subscription.They followed three practical habits.
1. Use Expensive Models for Planning, Not Every Task
The team didn't rely on its most expensive model for every operation.Instead, it separated responsibilities:
- Advanced models handled complex planning and important reviews.
- Less expensive models handled suitable implementation tasks.
- Routine operations were delegated whenever possible.
For example, designing the architecture of a complex application may justify a more capable model.
Renaming variables, generating straightforward boilerplate, or performing a simple formatting task usually doesn't require the same level of reasoning.
The goal is to match model capability to task complexity.
However, model selection should also consider accuracy, review requirements, and the cost of correcting mistakes.
2. Turn Repetitive AI Tasks Into Scripts
Another important habit was identifying tasks that developers repeatedly asked Claude to perform.If a task can be expressed as a reliable script, there's often no reason to spend AI tokens performing it again and again.
Consider a project where you regularly need to:
- Rename files using a predefined convention.
- Generate reports from structured data.
- Format source code.
- Validate JSON files.
- Run automated tests.
Once implemented, a local script can execute without making additional AI requests.
It may still consume computing resources, but it doesn't require new model tokens unless AI calls are explicitly included.
A useful rule: If you repeatedly ask AI to perform the same predictable operation, consider automating it.
This makes development workflows faster, more consistent, and less dependent on token consumption.
3. Keep Project Context Consistent
The team's third habit involved maintaining a stable working environment.Rather than unnecessarily rebuilding project context, they kept frequently reused instructions and project materials consistent.
This matters because prompt caching depends on matching eligible prompt content.
Even small changes to cached portions can prevent reuse of an existing cache entry.
For Claude Code users, practical habits include:
- Keep stable project instructions in
CLAUDE.md. - Avoid unnecessarily rewriting instructions between requests.
- Keep reusable project context organized.
- Continue relevant working sessions when appropriate.
- Avoid repeatedly introducing large amounts of identical material without a clear reason.
Cache reuse depends on factors such as matching prompt prefixes, cache lifetime, and how the application manages caching.
Likewise, keeping a conversation open indefinitely doesn't guarantee better performance or lower costs.
The objective is to preserve useful context without accumulating unnecessary information.
🔍 How to Check Your Own Claude Code Token Usage
If you're using Claude Code, you can inspect your usage with ccusage, an open-source tool that analyzes locally available Claude Code usage data.Project repository:
https://github.com/ccusage/ccusage
If you have Node.js and npm installed, you can run:
Bash:
npx ccusage@latest Bash:
npx ccusage@latest daily Bash:
npx ccusage@latest monthlyPay particular attention to these metrics:
1. Cache Read Tokens
How much of your reported token activity comes from cached content?
2. Cache Creation Tokens
How much new content is being written into the cache?
3. Input and Output Tokens
How much uncached input is processed, and how much new content does the model generate?
4. Estimated Cost
What would the recorded usage cost under the pricing assumptions used by the reporting tool?
Remember that estimated API costs aren't necessarily equivalent to actual Claude subscription charges.
⚠️ Does a $200 Claude Subscription Replace a $9,000 API Budget?
Not necessarily.The team's experience is an interesting example of efficient subscription-based AI development, but it shouldn't be interpreted as a universal pricing guarantee.
Claude subscription plans and API usage have different billing structures.
A subscription doesn't provide unlimited API access, and usage may be subject to limits that vary depending on the plan, model, demand, and other conditions.
Likewise, the team's high cache-read percentage doesn't guarantee that another developer will achieve identical results.
Actual usage depends on factors such as project size, workflow design, model selection, and how frequently context can be reused.
The valuable lesson is not that every developer can replace a $9,000 API bill with a $200 subscription.
It's that poorly managed AI workflows can consume significantly more resources than necessary.
Final Thoughts: Optimize Your Workflow Before Spending More
The team's report demonstrates how much token activity can accumulate during intensive AI-assisted development.But it also highlights three useful ways to improve efficiency:
- Use powerful models where their reasoning capabilities provide meaningful value.
- Replace predictable, repetitive AI operations with reusable automation.
- Organize project context to encourage effective prompt caching.
Look at your cache-read activity, identify repetitive operations, and check whether you're repeatedly processing information that could be reused.
Sometimes the biggest improvement doesn't come from buying more tokens.
It comes from using the tokens you already have more effectively.