
- by x32x01 ||

When an AI model generates a long response, does it recalculate everything it has already processed? Without an optimization called KV Cache (Key-Value Cache), it would repeatedly perform many unnecessary calculations, making text generation slower and more expensive.
KV Cache solves this problem by storing previously computed attention keys and values, allowing Large Language Models (LLMs) to reuse them instead of calculating them again at every generation step.
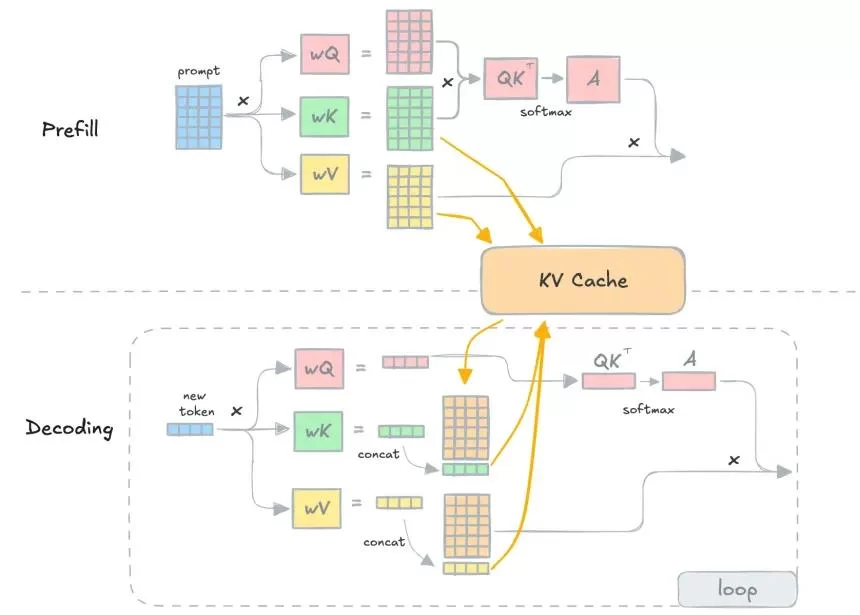
The model processes the entire input prompt, computes the Keys and Values for each layer, and stores them in the KV Cache.
2. Decode Stage
When generating the next token, the model:
Its memory usage generally increases with:
KV Cache is not permanent memory that remembers your conversations after a session ends. It is temporary computational storage used during model inference, not a persistent memory system for retaining user information.
💡 The engineering lesson: Improving AI performance isn't just about using more powerful GPUs. It also means reducing redundant computations and managing memory efficiently. KV Cache is a fundamental optimization that helps make modern Large Language Models practical to run.
KV Cache solves this problem by storing previously computed attention keys and values, allowing Large Language Models (LLMs) to reuse them instead of calculating them again at every generation step.
🧠 Why Do Transformers Repeat Calculations?
Models based on the Transformer architecture generate text one token at a time. During the Attention process, the model computes three main components:- Query (Q): Determines what information the current token is looking for.
- Key (K): Helps the model identify which previous tokens are relevant.
- Value (V): Contains the information used to produce the attention output.
⚡ How KV Cache Works
KV Cache stores previously computed Keys and Values for each relevant Attention layer, allowing the model to reuse them when generating new tokens.The process typically involves two stages:
1. Prefill StageThe model processes the entire input prompt, computes the Keys and Values for each layer, and stores them in the KV Cache.
2. Decode Stage
When generating the next token, the model:
- Computes Q, K, and V for the new token.
- Uses Q to compare the new token with previously stored Keys.
- Uses Attention weights to retrieve relevant information from Values.
- Stores the new K and V in the cache.
📊 Does KV Cache Save Memory?
KV Cache reduces repeated computation, but it consumes additional memory.Its memory usage generally increases with:
- Context length (number of tokens).
- Number of Transformer layers.
- Batch size.
- Number of Key-Value heads.
- Precision used to store cached tensors.
🛠️ How Engineers Optimize KV Cache
Several techniques help reduce KV Cache memory usage and improve inference performance:| Technique | How It Helps |
|---|---|
| Quantized KV Cache | Stores Keys and Values using lower precision to reduce memory usage. |
| Offloaded Cache | Moves cache data to CPU memory when GPU memory is limited. |
| Sliding Window Attention | Limits attention to a defined window of recent tokens in architectures that support it. |
| PagedAttention | Manages KV Cache in memory blocks to reduce fragmentation and improve concurrent inference efficiency. |
🚀 Why Is KV Cache Important?
KV Cache is one of the key optimizations that makes LLM text generation faster and more efficient. By reusing previously computed attention data, models avoid unnecessary calculations during token generation.KV Cache is not permanent memory that remembers your conversations after a session ends. It is temporary computational storage used during model inference, not a persistent memory system for retaining user information.
💡 The engineering lesson: Improving AI performance isn't just about using more powerful GPUs. It also means reducing redundant computations and managing memory efficiently. KV Cache is a fundamental optimization that helps make modern Large Language Models practical to run.